[ Home ]
[ aca / en / f / h3 / i / jp / t / v ] [ dis ] [ Home ] [ FAQ ] [ Rules ] [ Catalog ] [ Archive ] [ RSS ]
Board Statistics
Board PPD Total Posts Unique Posters Last Post
Take it easy!

old.hikari3.ch will be permanantly shut down soon

(unrelated to countdown)
Loading...
image.png - 6059.29 KB (3000x3086)

TRICK OR TREAT SMELL MY FEET

Your fortune: Outlook good


9f71fe1a6d632f0fd4aac624ba1ab980.png - 2117.09 KB (1771x2508)

I'm opening my inbox right now shadesshadesshades 2k new mails drool I'm so hyped up to see all of the things my friends wrote to me love!!!!!! >mailing list >mailing list >mailing list >mailing list >mailing list >mailing list >mailing list >mailing list >mailing list >mailing list >mailing list >mailing list >mailing list I haven't checked those in years?????? crycrycrycrycrycrycrycrycrycrycrycry

Your fortune: Very bad luck

>>

Nobody likes you.

>>

>>13367 Yes but why!?vengence


babyraemmo.jpg - 377.57 KB (643x617)
>>

>>13326 your wife? but shes with me right now

>>

>>13327 your wife?? that's my wife! get your own!! angry

>>

If she's yours then why did I see her in MY computer?

>>

>old.hikari3.ch will be permanantly shut down soon I didn't even know it was there, but I do miss the old hikari look.

>>

>>13364 There is a site theme for that. The theme selector on the sidebar has a classic option. happy


Screen Shot 2026-03-02 at 4.18.40 PM.png - 444.29 KB (2003x1640)

So I've been working on a project to create a singing voice synthesizer I'm basing it on the description in Jordi Bonada's PhD thesis "Voice Processing and Synthesis by Performance Sampling and Spectral Models". After a lot of trouble with getting TWM f0 estimation to work, I've finally gotten to implementing MFPA (Maximally Flat Phase Alignment". And amazingly, it seems to have worked first try. Compare my results: https://i.ibb.co/dsvgv0fd/Screen-Shot-2026-03-02-at-3-54-48-PM.png To the results in the study: https://i.ibb.co/C3fjdWVd/Screen-Shot-2026-03-02-at-3-55-09-PM.png

>>

>>13286 Actually, thinking about it, the resilient border interpolation at synthesis is not unnecessary now given by proposed WBHSM+LPC framework. The reason it became unnecessary before is that the proposed RVPM modeled each voice pulse as its full impulse response, assuming a time-invariant filter for each pulse (although I suppose the EpR differential envelope may model some of the time-variance of the filter, but this breaks as transforms are applied). The new WBHSM+LPC model is a literal combination of WBHSM and LPC where WBHSM models the source signal. Since that signal is not filtered, each voice pulse is actually independent, and pulses and periods are truly equivalent. Because of that, we actually go back to modeling each individual pitch period, reintroducing the need for the synthesis border interpolation. For this, we can do the same thing we do in the analysis stage where we shifted the window such that the window starts coincides roughly with the glottal opening instant and only the right side of the window is interpolated. This becomes especially beneficial for the WBHSM+LPC synthesis since the left side is where the voice pulse actually is, while on the right side the glottis should be closed or almost closed.

>>

Actually there's an alternative to converting the parallel filter to cascade filter, which is just to keep it as a parallel filter. How this can be done I will describe shortly. This may be preferred as I believe not all allophones can be modeled well by cascade filters. Furthermore, perhaps higher resonances can't be at all in general. The parallel filter is just a sum of resonances, which are each linear-time invariant filters, thus it is also a linear-time invariant filter and thus also can be expressed as a z-transfer function. This can be done in practice by starting with a z-domain expression of the collective z-transfer function, in the form of a some of all the composite z-transfer functions. Then, each of the terms are refactored such that they all have an identical. Finally, all of the numerators can be summed. Much of the terms can then be combined since they are just constants times some power of z. The result is an IIR filter. We can use the decomposition property of IIR filters that lets us turn one into an all-pole IIR filter and an FIR filter that represents the zeros. We do the inverse filtering step using the former. Finally, we add an additional step in the second WBHSM pass where we divide the spectrum by the latter's frequency response.

>>

Hello, As you may know, I am working on a project relating to voice signal processing. There several goals to this project. One is creating a general voice signal processing software library; another is creating a realistic singing voice synthesizer based on said library. However, a side project of this project has been recreating the VOCALOID2 synthesis engine. Previously, I have discussed this, but I had yet to really attempt it specifically. Recently though, I made a breakthrough that has been an impetus towards actually doing it. This breakthrough was not a scientific breakthrough, but simply something I found about. Previously, I did not attempt this because I realized I'd actually need to obtain the VOCALOID2 software to have a good chance at doing this. Previously, I had hoped that I'd be able to find clean raw audio of VOCALOID2 output online and compare it to my results. However, I quickly realized this was not enough. First, I couldn't actually find that much. Although the little I did find was quite helpful (it was the basis of my last post on pitch and dynamics models), I quickly realized I'd need a lot more, and would need agency to test specific things. Furthermore, I'd need the specific database to test. The VOCALOID2 software has not been available for sale for over a decade. One option would be to order a physical copy, but these are hard to come by. Besides, it requires internet activation to install, which cannot work now since the activation servers have been shut down. Although some voice libraries are still available, these require the software itself as a prerequisite. However, I found out after some research that apparently demo versions of voice libraries actually come bundled with a limited version of the actual software. It seemed unlikely though that any of these would still be available. However, after a quick search I found one that was surprisingly still available. After signing up, I was able to download it. Indeed, it did not require online activation. However, the installer would fail to start, without giving any error message. I tried just about every trick in the book, however none worked. I even tried https://github.com/lifenjoiner/ISx as an attempt to directly extract files to install manually, but that also wouldn't work. Finally, I moved the installer out of the directory it came in, which contained invalid characters. I thought I had already tried this, but it seems I hadn't, because it worked perfectly following this. So recently, I have been working on the VOCALOID2 recreation. The basic idea was to implement it based on papers and patents, implementing several possible variations in cases of uncertainty. The VOCALOID2 software would be used as a reference to compare the outputs to, and also to decide the few things that weren't really mentioned in papers or patents. The latter was basically just the pitch and dynamics model, which is the single most transparent thing since it can be analyzed just by analyzing the resulting synthesis audio. Already, a database parser has been implemented in C, that parses the VOCALOID2 database format. That format seems to be known as DaisyDB, according to figures in Bonada's PhD thesis, so I have named it accordingly. Although I expected the process to be a huge hassle, it actually turned out to be surprisingly easy. Basically, just by spending a couple days in a hex editor, and cross referencing it with papers and patents, I was able to decipher pretty much the entire format. The parser can already parse whole databases without issue, and there are only a handful of fields whose use is not yet known, many of which I expect will be resolved in due time. (continued in next post)
>>

(continued from previous post) Anyway, the main focus of this post is something I just realized something about the frequency-warping rendering variant of the Spectral Peak Processing algorithm (alternative strategy 4/e, p. 89 of "Voice Processing and Synthesis by Performance Sampling and Spectral Models, https://www.tdx.cat/bitstream/handle/10803/7555/tjbs.pdf). This is of significance because I suspect that variant may have been used in VOCALOID2. This is for several reasons. First, it is the only one of those alternative rendering strategies that was patented ("Pitch converter", Bonada et al, JP4840141B2; now-expired)*, and said patent was filed in 2004. The latter detail is important, because I have already deduced that the VOCALOID2 engine must have been completed from between late 2004 and early. This can be seen from two angles. *A later patent ("Singing composition device and singing composition program"; Bonada, Loscos, and Kenmochi et al; JP4839891B2; now-expired) proposes another technique distinct from all those mentioned in thesis; however it was filed in 2006. On one hand, as I discovered yesterday, VOCALOID2 actually uses the Maximally Flat Phase Alignment algorithm. This seen based on the fact that what I have deduced to be an MFPA harmonic envelope is contained within the SPP frame analysis data within the VOCALOID2 DaisyDB database format. Each SPP frame has chunk identifier "FRM2", presumably meaning "Frame version 2". In Bonada's 1997 Master's thesis ("Desenvolupament D’un Entorn Gràfic per a L’anàlisi, Transformació I Síntesi De Sons Mitjançant Models Espectrals"), a chunk-based hierarchical format is described. In that format, chunks were also assigned four-byte identifiers, and the identifier for the frame chunk was "FRM1". So the "FRM1" vs. "FRM2" distinction could refer to the iteration of the spectral processing technique; the distinction of SMSTools vs. SMSTools2, or perhaps just different iterations of the storage format. I was able to determine that it was an MFPA envelope because it was exactly equiv to a linear phase shift applied to the harmonic phases, plus phase unwrapping. Furthermore, it could not have just been the method wherein the harmonic phases are shifted such that the fundamental phase is zero (such as in "Spectral Approach to the Modeling of the Singing Voice", 2001, Bonada et al.), because the fundamental phase was non-zero. The MFPA algorithm was first proposed in the paper "High Quality Voice Transformations Based on Modeling Radiated Voice Pulses in Frequency Domain" (alternatively titled "High Quality Voice Transformations Based on Modeling Radiated Voice Pulses in Spectral Domain"), published in October of 2004. On the other hand, the patent for the first iteration of the Bonada 2005 expression system (JP2006330615A, now-expired) was filed on May 30, 2005. Since this was the main improvement for the third iteration of the VOCALOID, and, I discussed previously, VOCALOID2 did not use it; this means the VOCALOID2's engine must not have been finished any later than that date. (continued in next post)

>>
IMG_6526.jpeg - 579.76 KB (1861x1442)

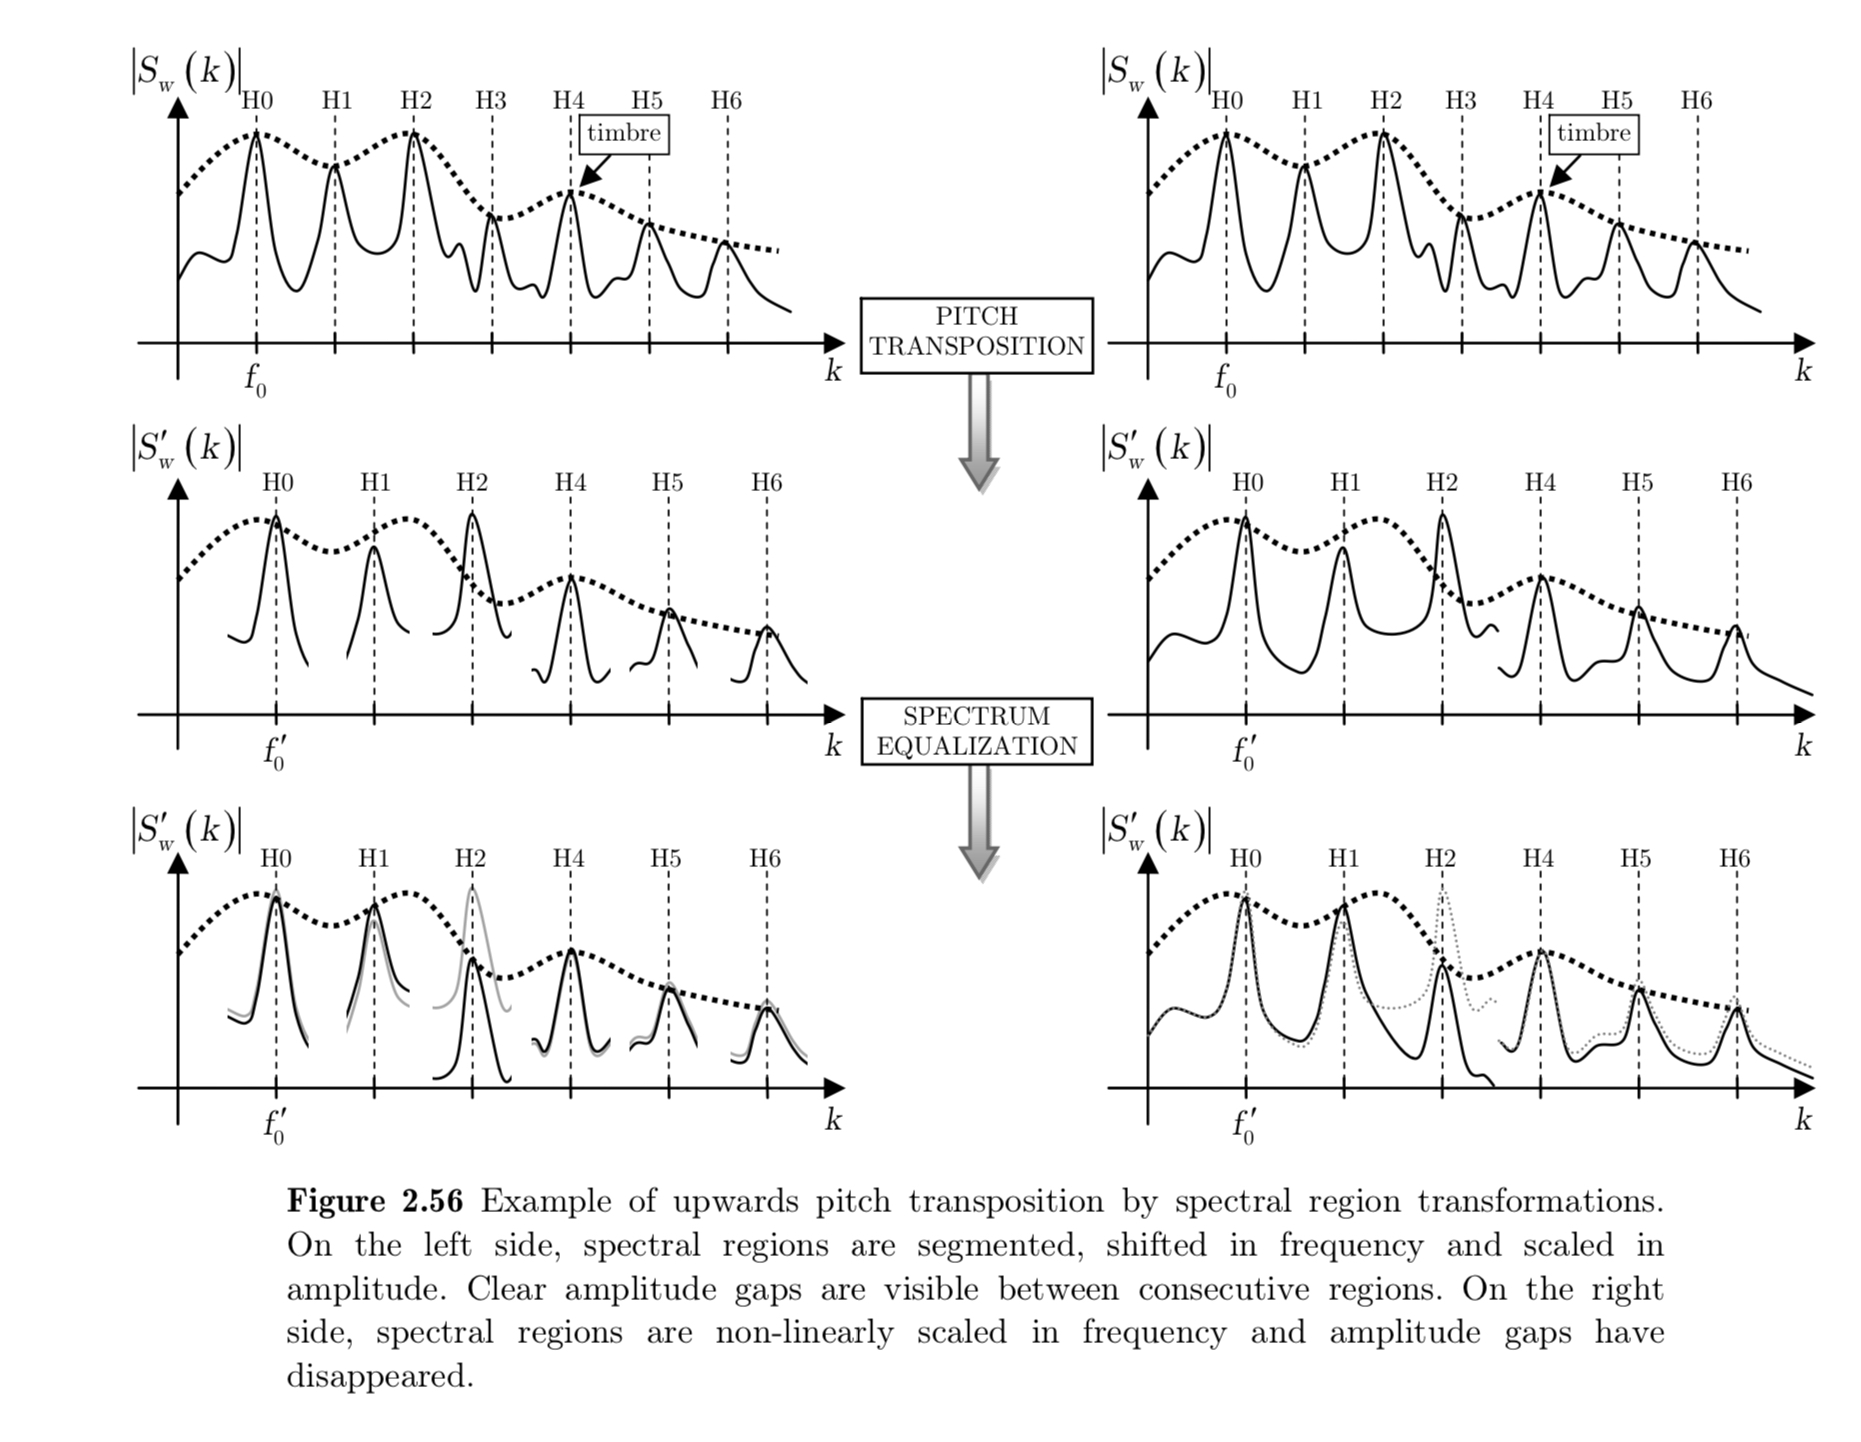
(continued from previous post) Anyway, onto the main topic of this post, which is what I just noticed about the figure in Bonada's thesis (which was in turn copied from "Improvements to a Sample-Concatenation Based Singing Voice Synthesizer"), picrel. At the top, we see the original spectrum and its harmonic envelope. In the middle plot, we see an intermediate visualization of peaks after being moved, but before equalization. Notably, there now exists one discontinuity due to one peak being used twice. In the bottom plot, we see the rendered spectrum after equalization. Notably, there is still only one discontinuity in the spectrum. The proposed technique eliminates gaps in the spectrum, but not discontinuities, because the SPP algorithm, as described, regardless of the rendering variant, scales all the bins in each region, which would produce a discontinuity at the boundary between regions. Instead, in the bottom figure, the amount of scaling appears to vary non-linearly, such that it is continuous. This is especially apparent since the figure shows a dotted line representing the spectrum before equalization. You could say that this is just how the figure was drawn, however it is highly consistent across the whole figure; furthermore, it is consistent with other papers and the descriptions in some of the patents seem to suggest that the amplitude discontinuities may be solved. Based on this, I have a hypothesis on how the non-uniform amplitude scaling may have been implemented. The process would be to create a first envelope of the harmonic peaks before transformation; create a second envelope of the harmonic peaks after frequency shifting, but before equalization; and finally scale each bin based on the ration of the first envelope to the second envelope. Although I have not tested it, looking at the figure visually, the proposed procedure would seem to match very closely, assuming a smoothing interpolation. Furthermore, it may also explain why the intermediate stage that shows the spectrum after shifting, but before equalization, is explicitly shown. Such a thing is not actually created by the SPP algorithm as described, but it does make sense to show for the proposed non-uniform amplitude scaling. Finally, in theory, this procedure would not produce any additional amplitude discontinuities, further consistent with the figure. I will implement this idea as a variant in my existing SPP algorithm, which has already been implemented such that multiple variants (and combinations thereof) can exist in the same procedure (using preprocessor flags). Furthermore, I will consider the possibility that the same procedure is also used for the unwrapped phase envelope.


twitter_1970405976588394832.gif - 383.37 KB (498x370)

was wondering what you guys listen to on a daily basis.. do you guys use spotify or soundcloud or other streaming apps? physical, maybe? i listen to "everything", but mostly a lot of shibuya-kei/rock/rhythm game music happy2

>>

I mostly listen to whatever my gf buys off of bandcamp that I can leech off of desu

>>

>>12088 what does she buy off bandcamp? also why is that your main way of acquiring music laugh

>>

>>12090 Mostly some variety of electrronic stuff. She's been pretty into minimalist synth lately in particular. I tend to mostly listen to music like this just cuz I know she has good taste and if I ever want an album to put on I can grab smth from her account since she buys lots of music. I do also use soulseek to download other music tho...

>>

I likes the electronics music are fun neco_arc

https://youtu.be/zJTH02yueg0 [Embed]

>>
https://www.youtube.com/watch?v=CjAk_ut6nW0

neco_dance


fmu0xausflae1.png - 2385.73 KB (2184x2072)

Any other hikarians who suffer from speech impediments? What impediments do you have? When did it start? How do you cope? How many times do you wish death upon yourself when you're forced to speak publicly? How do you think it affected your life? I'll start: >What impediments do you have? stutter / stammer + heavy blocking >When did it start? as long as i can remember >How do you cope? obv i re-arrange my sentences and use synonyms but when i have to say a specific word that ik i will stutter in i try to skip or say the first syllable in a quieter voice this trick rarely works tho because i don't have a great control over my voice >How do you think it affected your life? ofc it made me make almost 0 friends as a kid because everyone thought i am a weird retarded kid because i sound like one hence i deserve to get bullied but actually now that i think about it, the lack of friendship was actually valuable cuz it made me develop skills and hobbies that i wouldn't have had time to

>>

>>11979 >Alogia Not sure of i have this or just a very low verbal iq (even though i speak 3 languages "fluently")

>>

personally i don't know if i have a stand alone speech disorder but autism + adhd give me a hard time finding words, pronouncing them right, not stammering and then getting the whole sentence out. more often than not i fuck up one word and then have to restart the entire sentence over and over until i get it out one time fully start to finish without fucking it up

>>
6e043b1543e4a87426c2c871c5bded9b.jpg - 48.84 KB (736x414)

I have a British accent In all seriousness though, I fumble and mutter a lot in casual exchanges, especially in my mother tongue. I can roughly tell when a social cue is dropped, just can't grasp the words and cultural sentiment to respond to it properly. It is easier for me to react to such cues in English, but even then I'm not what you'd call "socially fluent". It's a bit uncanny because this isn't a case of being raised multiculturally, by migrant parents in an English-speaking country, or what have you. I just taught myself English from a very early age, and I do mean like from 7 or 8 yrs old (TV and internet, of course). In spite of the aforementioned, I can project my voice clearly during presentations no matter the language, so it only applies to casual situations. I don't think this is considered a speech impediment as such, but figured some hikarins might relate to this. The notion of finding it easier to communicate certain things in acquired languages is understood and not uncommon. I just think my case leans toward the more extreme end where my native fluency is effectively eroded.

>>

>>13325 I gross at 90% of standalone expressions in my native language, like what do you mean "i love you" disdain, bitch you sound like a hog in heat
>>
image.png - 136.57 KB (239x501)

oh hey this thread is still up >>13321 >very low verbal iq Well it greatly depends! verbal iq mainly relates to how you process the intake of language, so low verbal IQ does impact expression. However Alogia is something that happens with language production and people with alogia tend to be able to understand language like "normal" ""people"". Id say the best rule of thumb to know if you have alogia is if your able to understand something down to the dot but have difficulties expressing it, say for example if you have difficult times on sudden questions versus paced conversation. wink

Your fortune: Good Luck


oops.jpg - 37.62 KB (583x608)

Ah shit I overslept for a bit

>>

Is the thread op stuck at the top of the homepage new posts forever? lol

>>

>>13351 Well, it is technically the newest post on the site

>>
1000021497.jpg - 151.92 KB

>>13351 that's actually hilarious lolol snickersnicker

>>

>>13299 J-JOHN TITOR!???!?!?!

>>

>>13350 Mikuru-chan is an angelhappy


1000003046.png - 1425.03 KB (800x955)

It's so fucking cold man

>>

Wish I was you right now, it's so fucking hot right now.

>>

>>13348 aussiefag.

>>

>>13349 It was 18° in Canberra today, that's cold


61ddbd7f7ad52d55ad511987ee4847d29c843fed61de9012594ae1d31b82e892.jpg - 219.98 KB (600x412)

What's hikarin's favorite soda?

>>

>>13094 im sippin on some A 'n' dubya

>>
mayushi dk pepper.png - 630.85 KB (1280x720)

>>13126 really, a scientist's fuel its my favorit 2! esspecialy the vanilla float flavour

>>

>>13330 actual coke floats (coke with scoops of vanilla ice cream in it) fucking suck though.

>>

>>13338 honestly i have never had a float made with coke. root beer just seems so perfect for the job.

>>

>>13345 Not that anon but I tried to put a scoop of vanilla ice cream into my Coca Cola once, taste was insanely bad and it also made some sort of weird grayish foam, I don't know if my ice cream was just low quality but it truly sucked Also, Dr. Pepper Strawberry and Cream is the best soda flavor I ever tasted


1533366125612372.jpg - 269.96 KB (2048x2048)

how do i use those emoji thingies? t. retard

>>

Dis nyagan 4 reel?

>>

snicker

>>

laughlaughlaughlaughlaughlaughlaughlaughlaugh >>13337 nice gigal33t


Delete post: [ File only ]